
Imagination Technologies is extending its GPU architecture further into AI, arguing that more edge-AI workloads can be handled by the GPU rather than by increasingly large, dedicated NPUs. Kristof Beets and Vitali Liouti explain how the company’s converged-acceleration approach builds on existing PowerVR strengths in locality, memory efficiency, and programmability, while adding support for LLMs, neural rendering, and other AI workloads.
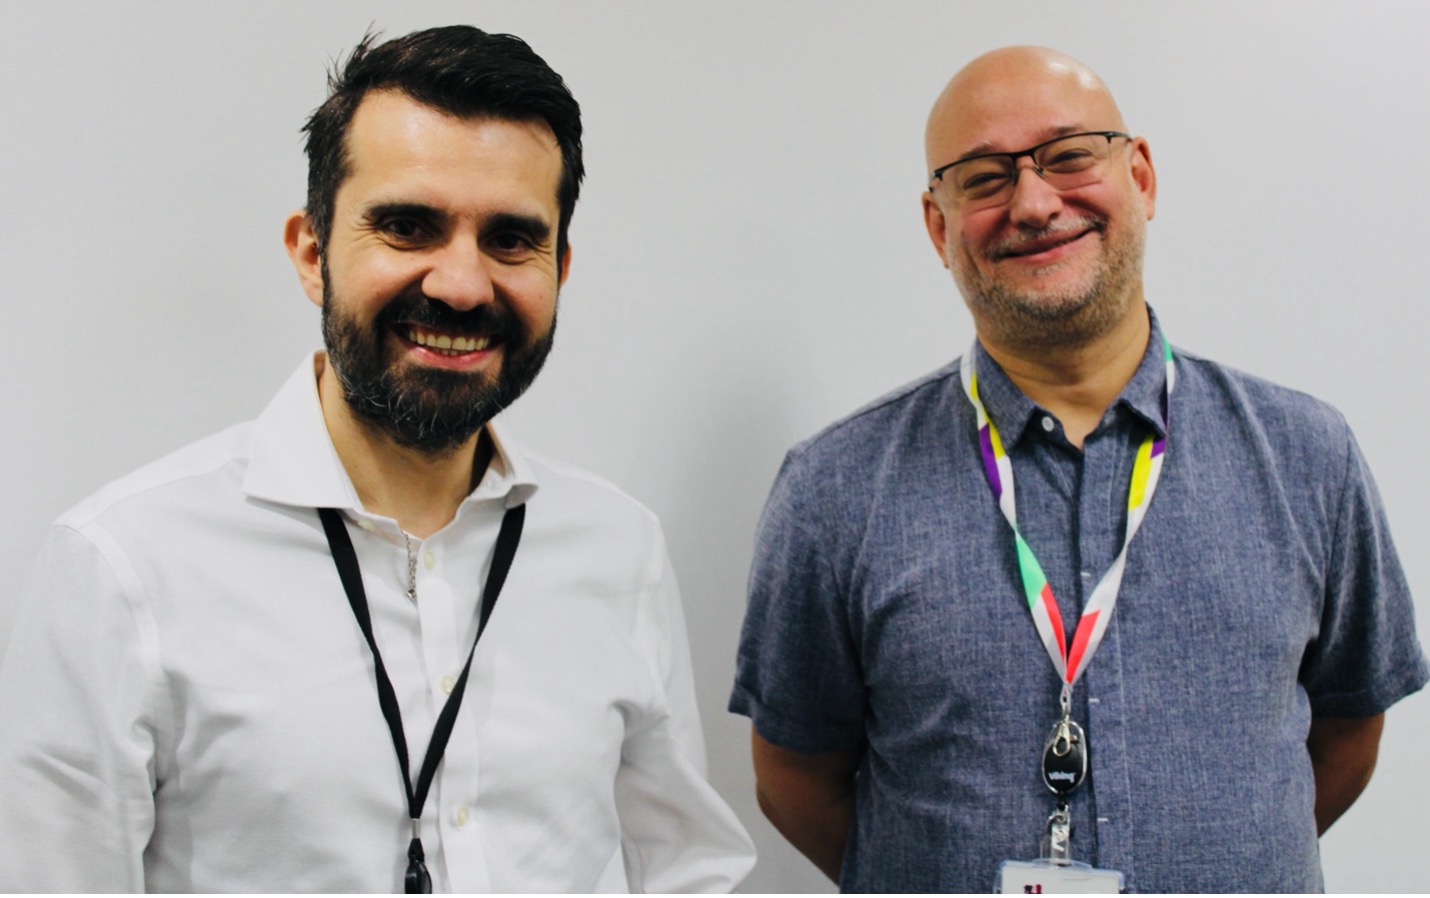
Vitali Liouti (left) and Kristof Beets (right). (Source: JPR)
Second of a two-part series of interviews with Imagination Technologies.
Imagination Technologies believes the balance of AI processing in edge devices is beginning to shift. Rather than continuing to add increasingly large dedicated accelerators, the company argues that more AI workloads can be absorbed by the GPU.
In this extensive interview, VP of Product Management Kristof Beets and Senior Director of Marketing & Revenue Operations Vitali Liouti discuss Imagination’s converged-acceleration strategy, the limits of dedicated NPUs, memory efficiency, LLM performance, neural rendering, and how the company sees its GPU architecture evolving for the AI era.
You launched a new product with some AI elements. What’s the problem you’re trying to solve with it?
Kristof Beets: The key thing we’ve jumped onto is, how are we going to tackle AI going forward?
The easiest way to look at it is mobile SoCs. You see DSPs, NPUs, CPUs, and everybody is pouring in AI acceleration. If you take one of the latest Qualcomm ones, you have a GPU with 18 MB of SRAM, an NPU with another 16 megs of SRAM, and a CPU subsystem with 32 MB of SRAM. At some point, that’s just not going to work. It’s too expensive. Customers will effectively have to make choices.
We think the GPU is in a very good position for that because a lot of the AI and compute work inherently starts from GPU. All the new research is done in open source as well, and it typically has a GPU backend. The chances that it has a dedicated DSP backend are almost zero. NPUs have dedicated tool flows, again with no real backend. So the GPU is the easy way of getting stuff running.
The CPU is the alternative, but the CPU is really optimized for single-thread performance and decision-type workloads. Arm has now put an accelerator core in there, but if you look at where it’s integrated, it’s connected to an L3 cache. It’s a bit like having a far-away accelerator hanging off it. It doesn’t really make sense.
So the GPU is very well-positioned. That’s really the journey we’ve started with what we call converged acceleration on the GPU, where we try to make most of that investment universal—adapting logical things from the NPU into the graphics core.
As an outcome of this, are you expecting people potentially not to have an NPU in the system? Or are you saying you can shift the balance and get more done on the GPU but probably still have all the other pieces?
Beets: It’s an evolution. We have a number of customers that, for cost reasons, are looking at substituting the NPU with a larger GPU, or using the same GPU differently. In other markets, it’s more a collaboration. The key thing is that an NPU makes sense if it stays very focused—almost a fixed-function acceleration core for very specific use cases. In autonomous vehicles, for example, some of the vertical players know exactly which algorithms they want to run. They can tweak it and control it. There, an NPU makes sense because it delivers power-efficiency and bandwidth benefits by not trying to make everything programmable—because once you do that, it starts looking like a GPU.
The other element we’ve invested in is collaboration: how we work together using on-chip SRAM, shared buffers, and hardware-based handshake signals, with our RISC-V engaging directly with that NPU. Then you can do fine-grained overlap between the processing.
Vitali Liouti: Despite the growth of dedicated AI accelerators, the GPU still takes a large portion of the die area of a flagship phone. We’re talking larger than the CPU and the NPU even in coming years. That signifies how important it is, but it also means it’s an area worth utilizing. You’ve already spent that silicon on graphics, so you can use it for AI.
In cases where you want something heterogeneous, it still works because the GPU collaborates with the CPU and NPU to provide enhanced performance. But when you’re more restricted, you can use the GPU to do a lot of those things through that -ed acceleration concept.
It feels like you’re saying the balance should shift towards the GPU, with more AI done on the GPU. How do you feel about the risk that people on the other side say neural rendering is huge now, and maybe the future GPU is actually an NPU? Perhaps the balance shifts completely the other way, towards an NPU that does rendering as well as everything else.
Beets: In a sense, both of them would move towards the same place. It’s a lot easier for us to deal with rendering because we already have the classic fixed-function hardware. If, at some point, the answer becomes that you can delete some of that, it’s fairly easy to do. Whereas with an NPU, if you have to add texturing pipelines or anything else, that’s much more of an uphill battle, both in terms of patents and simply doing the work.
But the fact that graphics is no longer just graphics is another key reason the GPU has no choice but to adopt AI. We see that from most vendors now. They’re finally saying, ‘I used to be heterogeneous, but I have no choice. I have to put these things in the GPU because otherwise these use cases don’t work.’ That’s another reason the GPU stands in a good position ultimately, because graphics is no longer pure graphics. It’s graphics with integrated AI.
The initial steps were things like superresolution and frame generation, which technically you could off-load to an NPU because they’re phased executions. But now you see things such as neural compression of textures. You start to see shaders and shading effects being mapped onto small neural networks. Then it doesn’t work to do a little bit, off-load it, and pull it back. It’s too inefficient.
AI-related rendering workloads clearly make sense. What other workloads have high utility? Do you expect essentially any edge-AI workload to run on the GPU?
Beets: If you look at phones or laptop-type devices, UI rendering, especially on phones, fundamentally needs maybe a single USC. On a laptop, it’s similar. You might need multiple units if you have lots of screens, but it’s still a tiny fraction of the GPUs deployed in mobile phones or laptops, because those GPUs are designed for high-end gaming. For your desktop interface, you don’t need all of that. And typically, you’re not doing heavy AI at the exact same time that you’re doing the user interface. That means on one of our eight-core implementations, you could have seven out of the eight units effectively available for AI. In something like a laptop, you could have 15 out of 16 units available. That’s quite a lot of compute, especially with dedicated acceleration cores.
One of the things I wonder is, to what extent this new architectural model extends the early advantage of the Imagination graphics architecture—the tile-based rendering concept.
Beets: The key difference is that there’s an amount of fixed function involved with tile-based rendering, such as the sorting of geometry. That concept doesn’t really exist in compute. The benefit is the similarity in the hardware you already have. Our hardware already contains the concept of tile memory. That makes reuse and flexibility much easier because the concept is already there. We already have memory for that; now we can give it dual purpose. That’s the main alignment.
Is it genuinely dual-purpose, or have you increased the amount of memory?
Beets: It depends. Most of the memories are multi-use and fully under software control. The other reason we’re well-positioned is that our architecture inherently has quite a lot of register space. We have about half a megabyte of register space for every USC. Compared with the mobile or embedded competition, that’s probably two to four times more. It’s much more in line with some high-end desktop parts or even compute desktop and server parts. So again, that puts us in a good position. We don’t need to add more memory. There was already enough in the design.
Apple emphasizes that its architecture inherently has memory advantages because of shared memory, reduced data movement, and the way the system is designed. What is similar or different between what you’re doing and what Apple has been doing?
Beets: Apple’s key benefit has always been full-system design. Their GPU sits next to a massive system-level cache (SLC), and managing that intelligently is the good part. We’ve had customers put equivalent amounts of memory down, historically called a system-level cache. For some use cases, that makes sense. In graphics, caching is the right answer because you don’t know exactly which objects will show up where, or which textures or resources you need. It depends on where you’re looking.
AI and compute are very different because you know exactly which data you need. You can do much more preloading and prefetching. You know exactly which data you will reuse because there’s not much branching or dynamics in AI. You’re repeatedly executing the same layers. That means these SLCs don’t necessarily act as caches. They become more like software-controlled buffers. If you can make that a universal resource, that’s the benefit. That’s also why we’ve kept a lot of that memory outside our GPU. If you still have an NPU, it can use it. If the GPU wants to use it for AI or graphics, it can do that. It becomes a generic resource.
That has been one of the big problems with a lot of DSPs. They have tightly coupled memories, but those memories are only usable by the DSP. That multipurpose approach at the system level has always been easier for Apple to exploit. We offer that flexibility to our customers; whether they deploy it is the nature of being an IP company.
So it sounds as though you potentially have an Apple-like caching system, plus fairly large memory inside the architecture. How distinctive is that?
Beets: Everybody is moving in the same direction but maybe not to the same level. What we’ve seen from embedded providers has generally been fairly modest inclusion of AI. If you look at Arm, for example, it’s very limited. It supports INT8 and INT16 data types, which is fairly old-fashioned now. It’s quite loosely coupled and further away. It’s about a quarter of the performance we have per core. It feels more like dipping your toe in. We’ve gone quite heavily after LLM and other use cases, rather than simply saying, ‘We’re going to do a bit of superresolution.’
Qualcomm has put matrix engines into Adreno, but, as always, they share very little beyond saying, ‘We’ve done this cool thing.’ It isn’t clear exactly how fast or capable it is. But again, it looks relatively midsized in terms of where it’s connected. Most of them connect to what we’d call the L1 cache. That means you’re still quite far away from your actual ALU pipelines. Then it becomes more of a layer-execution model rather than true, fully interleaved graphics and AI processing.
Liouti: We definitely share similar goals with OEMs such as Apple in wanting the architecture and products to be as efficient as possible. Memory has become increasingly important and much more expensive, especially in lower-end devices. We’ve gone from memory being perhaps 15% of the BOM to potentially 50%. Doing more with the same amount of power and the same amount of memory is, therefore, a core objective, and we’ll continue doing more with each architecture.
At the same time, if you want to distill our product strategy, it’s about being as programmable and flexible as possible. We do that through extensive support: FP8, FP4, MX formats. We want to be flexible enough for every developer to create and develop what they need, while also maintaining power efficiency. We’ve developed technologies such as the burst processor to extract as much as possible from the same resources. And, ultimately, we want to be as performant as we can be. At some point, TOPS stops mattering quite as much, and we’ve arguably reached that point with this architecture, even though we’ll likely increase it again in future iterations.
That’s the classic tension in AI between flexibility and fixed function. What are you seeing in the market, or in segments where you want to succeed, that tells you flexibility is the right story?
Beets: The biggest conflict we see is that the GPU brings standardization and flexibility through the programming model. A lot of people have gone heavily in the NPU direction. They have large investments accumulated over many years, but it can be painful. At some point, that pain keeps growing. It becomes more expensive and harder to support compared with moving towards greater standardization.
The difficulty with full replacement is that people say, ‘But we have our own thing.”’ Then you get internal pushback from those groups. But what you start seeing is people higher up in the organization, who need to make financial decisions, asking, How much does this cost? How much dedicated memory do we need? What are the pain points? Today, they might look at the GPU as the flexible option and put a toe in the water. Over time, we expect that ratio to shift.
Historically, Jon Peddie Research has not been a big believer in NPUs as the long-term answer across the market.
Beets: It depends on the ecosystem. In autonomous vehicles, where it’s very vertical and you know exactly what you’re going to do, an NPU can make sense because you can make it extremely efficient. The moment you have an open ecosystem, it starts to fall apart. We’ve seen that with Google TPUs. Nobody really knows how to program the thing unless you can use the tool flow or run something that has effectively been pre-chewed for you. Whereas with a lot of what we’re doing now, you can take the common tool flows and they more or less work out of the box. Because it’s open source, enhancements can be upstreamed so it works better out of the box for customers. You don’t need proprietary libraries or extensions.
That has also been a key difference versus Arm. Arm came up with custom Vulkan extensions saying, effectively, if you want to use our accelerator, you have to use these. We’ve taken the view that cooperative matrix, cooperative vector, and the newer standards are the right way to do it. That fits the principle of things working out of the box. If we created our own proprietary thing, nothing would work out of the box.
What gains are inherent in this new architecture? What does it deliver in performance, and how can customers expand on that through the rest of the system design? Also, could something such as a chiplet boundary reintroduce costly data movement that you can’t control?
Beets: If you look at LLMs—and this is true for other use cases as well—you tend to have two buckets.
Prefill is very compute-heavy. That’s where the neural or matrix engine gives you acceleration. That’s where you get the faster performance because we’ve put dedicated instructions in which run at a much higher rate than what we had before.
Decode is almost the opposite. Decode is very bandwidth-heavy. That’s where you depend a lot on the system. How are you doing caching? How much on-chip memory do you have? How much can the GPU absorb? This is one reason you don’t see us quoting tokens per second as much, because it depends. In a mobile phone you may have 100 GB/S. In a laptop, perhaps 200 GB/s. In automotive, you may have a lot more. A lot of decode performance will depend on that system execution.
The key thing is how fast we can move data in and out. On this latest series, the GPU can consume something like 768 GB/s at 1 GHz. There’s a lot of potential there, provided the system can deliver it.
Another complex decision, if you’re building a system with both an NPU and a GPU, is finding the correct ratio. We’ve seen people get that wrong. How much can I depend on my fixed-function hardware? How much flexibility do I need? Historically, everybody underestimates the need for flexibility. The GPU often ends up oversubscribed because there’s so much evolution, and because there are bugs in almost everything you do. Flexibility lets you work around bugs and problems. Something rigid and fixed cannot.
Where does the division of workload happen? Is that fundamentally a decision for the end customer—how to partition things between the GPU, NPU, and other elements?
Beets: Very much a workload and software-framework decision. Initially we worked with TVM (Tensor Virtual Machine), and TVM had a mechanism for deciding which layer gets assigned where. The answer is becoming more complex because it isn’t always simply, ‘This operation runs best there.’ Increasingly, the question is, Where is the data already?
Theoretically, you might identify an operation that runs better on another unit, but it may still be better to keep it local and run slightly slower rather than moving all of the data. The total result can be better. That’s where “AI schedules AI” becomes interesting. A lot of new work around optimization and scheduling, including work we’re doing internally, looks at using AI to do that. Old-style heuristics—generic rules that somebody came up with— re falling away and becoming much more AI-based, with systems trying to work out the right decision dynamically.
Liouti: That’s also where flexibility transcends the GPU. By emphasizing acceleration of prefill, we accelerate a lot of useful workloads. Vision is prefill-heavy. Agentic-AI usage is prefill-heavy. Anything ingesting a lot of data is prefill-heavy. There are also new models with little or no decode component. By making the GPU capable of doing many of these workloads much faster, we allow chipmakers and developers to choose more flexibly. That applies across all of our markets, and it’s extremely important in automotive, mobile, and consumer devices.
Let’s talk about neural rendering. What parts of image production are you enhancing or replacing with neural rendering today? What comes next, and what’s the limit of how much should be replaced?
Beets: When we used to work on frame-rate conversion, we dealt with people who would say, ‘We don’t really like that artifact there.’ You fix that one, and another artifact pops up somewhere else. There’s effectively no perfect solution. So we spent a lot of time focusing first on superresolution—taking the base image and scaling it up—because that’s much safer. The unique thing we’ve done is, again, about traffic to memory.
What we found other people doing—and you see this in algorithms from Arm and Qualcomm—is a preprocessing stage that looks a lot like graphics processing, then some AI processing, then some more graphics work. So you effectively have three individual operations to do superresolution. We’ve taken much more of a tile-based approach. We take a tile of the input image, along with the vectors and everything else we need, keep that fully on-chip, and generate the larger image. It’s a single pass combining all of that together.
The other important thing is that all the weights—the trained information—stay within the chip. We never need to refetch those. We’re not depending on the L2 cache to retain them. They load into local memory and stay there, which means it’s very efficient in terms of power and execution. It’s really building on locality and on the ability to intermix all these instructions.
How often do the weights change in this situation?
Beets: The weights themselves don’t. They’re the pre-trained part—effectively the neural network. On one side, you have the tile of image data, which keeps changing. The weights for the network that does the scaling stay fixed.
What we allow customers to do is retrain them. We’ve done generic training that works for most content. If a customer has a very specific game or type of content, they could retrain based on their reference images. That might produce a slightly better result.
Could a developer do that themselves?
Beets: Absolutely. There will be a universal pre-trained model and weights that we deliver, but the training flow will also be available to developers if they want to customize it.
So there’s still the equivalent of the old PowerVR SDK-type product?
Beets: Yes. It will all be open source. Windows tried to standardize superresolution, but that didn’t really work out. Vulkan has been discussing it for over a year, and we still haven’t seen anything emerge. So, everybody has effectively ended up saying, ‘Here is our library; it’s open source and you integrate it.’ We’ll also provide open-source Unity and Unreal plug-ins.
Liouti: We wanted to be very intentional about this. There are closed-source and open-source solutions that already do this, but we wanted something that was extremely efficient. We use multiple techniques to make sure it works well and can be used even on very constrained devices.
Beets: One thing unique to our training flow is self-compression. I’m not going to try to explain all of it, but the unique piece we can put into the customer training flow is that self-compression. It’s somewhat like doing your pruning during the training phase. It compacts the weights so we can keep them in the relatively small amount of on-chip memory.
Liouti: We have a paper on that. It’s quite an exceptional technique and relatively unique. It combines pruning and quantization. Being single-pass makes it extremely fast compared with other solutions, whether DLSS- or FSR-based. And because it can be retrained, developers can optimize for a specific use case, game, or whatever else they want. It’s a combination of techniques all pushing towards power efficiency.
Do you quote time per frame?
Beets: About 2.3 ms on one of the 64-core configurations at 1 GHz, which is relatively modest.
Superresolution is a fairly clean use case. But neural rendering is getting more controversial. Some developers hate it, some love it, publishers may love it. Do you philosophically have a line where you say, “This is what neural rendering should do, and this is where it should stop?” Or do you leave that to your customer or the developer?
Beets: Long term, it isn’t feasible for GPU companies to own everything. At some point, we have to hand it over to developers. For something like superresolution and frame generation, it may remain somewhat vendor-specific. That makes sense because they’re fairly universal techniques. But the moment you reach the point where you’re going to impact how the game actually looks, you’re on the wrong side of the barrier.
Our internal prototyping then becomes much more about teaching the training flows how to use self-compression so the data stays small, and how to execute efficiently. Ultimately, that comes back to cooperative matrix and cooperative vector standardization, because if developers face fragmented tool flows and different execution approaches, it becomes much less effective. Self-compression itself is universal. It can work across the hardware.
So Nvidia is on the wrong side?
Beets: They keep stepping over it, then they get a lot of backlash and tune it down. Ultimately, developers want to control that.
We’ve also looked at neural shading. Imagine a developer has written a shader that is thousands and thousands of instructions. That shader can become the input to your training process, and you try to compact that complex calculation into a much smaller neural network. There it becomes much more about the training flow, followed by executing that mini network efficiently.
How long does the training take? What is the actual work required?
Beets: Runtime and cost are not really the problem. Typically, the complexity is the training data. To some extent, that’s our issue: How do you get access to enough training data? But again, that tells you it should really belong to the developers.
Developers are already dealing with several kinds of neural rendering—DLSS and so on. Presumably, they’re already having to create training sets?
Beets: Today, most of that is delivered off the shelf by AMD or Nvidia. Everything we’ve seen until recently has been relatively safe from that point of view. Neural compression, for example, is essentially taking textures. It’s a variation on things like PVRTC (PowerVR Texture Compression) or ASTC (Adaptive Scalable Texture Compression). It isn’t fundamentally changing what the game does or how it looks.
What Nvidia did in the latest version gets closer to a beautification filter, and that becomes tricky because suddenly the character can look quite different from what the developer intended. That’s the point where you end up on the wrong side of the equation. If it’s compression or upscaling, you’re generally fine. If it’s frame generation and you aren’t generating too many artifacts, that’s also fine. But once you start changing the look and feel, that’s where you hit the conflict.
If we were doing a fair side-by-side comparison between DLSS and your Neural Super Resolution, what would we see?
Beets: Most of our training and judgment is done by running the content at full resolution, then comparing the upscaled output against the original. That delta is the main training signal. So we’re trying to stay as true as possible to what should originally have been generated, rather than teaching it, for example, that a face ‘should’ look a particular way.
But there are still trade-offs around fidelity, temporal stability and the usual complaints.
Beets: Superresolution is relatively manageable today because we control it. It’s a two-by-two upscale; there aren’t that many pixels that you’re inventing. That’s one reason we’ve spent more time thinking about frame generation. That’s where you get more streaking, ghosting, and strange temporal effects when things go wrong.
Again, we’re exploring a different approach. A lot of current techniques use optical flow as a separate operation. It’s separate processing, which then feeds into something else. We’re looking at whether the optical flow and motion analysis can be done by the network itself, so the whole thing becomes a single operation again.
Presumably you need history data?
Beets: Yes. On the input side, you need a larger window. But it depends on how you integrate it. You have the new current data on-chip. The history, by definition, is in memory because it came from the previous frame. We try to reuse what’s already there, but at some point you need to look back at past data to accumulate the information.
Where does global scene information fit?
Beets: These techniques tend to be image-based. If you go towards global scene information, you get closer to the discussion we had at the beginning—whether eventually rendering itself becomes neural. Then you’re talking about encoding a whole scene into a neural network and almost using it like a pseudo-ray-tracing engine, where the neural network tells you what color a pixel should be. That’s more in the area of Gaussian splatting and other techniques for encoding scene information into networks.
How do you sell this to a developer? How easy is it for a developer to get useful added performance, whether from the neural capabilities or E-Series generally? Why do they want this GPU rather than Mali or something else?
Beets: The developer probably cares about how difficult it is to use. A lot of the hardware benefits come for free through the compilers and the rest of the software stack. For superresolution, we’ve tried to be as standard as possible. We found that the most broadly integrated inputs were those used by AMD’s FSR algorithms. So we tried to make our inputs nearly identical. The idea is that if a developer has already integrated AMD’s approach, plugging ours in should be very easy.
Liouti: Go to almost any game now and you’ll find a selection of upscaling techniques. We want to be one of those options. We’ve started by producing plug-ins for Unreal Engine and Godot to support those markets, and we’ll continue using as much standardization as possible. Our ethos remains efficiency. We want our algorithms to be efficient. Some others may have an algorithm that costs a lot in power. For us, every watt matters. That’s how we build the products we build. The flexibility we’ve discussed throughout extends here as well.
Looking across E-Series, what is unique, patented, and difficult for somebody else to copy?
Beets: Quite a lot of the micro-tiling—how it schedules and is used in the hardware—has specific patents around it.
Probably the biggest other new thing is the burst processor—how that works and how it interacts with AI execution. The burst processor groups a lot of operations into a burst. That makes execution and control much simpler and more compact. A lot of things become expensive because of instruction decoders and constantly telling the hardware what to do. We keep that much cheaper and much more local with the burst processor.
If you look at AI processing, there are lots of tiles that need to ripple through all those operations. For us, that becomes a burst. All of that is grouped and bundled. Some of the instruction scheduling, and how we keep many of those tiles on-chip and deal with accumulation and buffer storage, builds directly on our tiling experience. We used to have multiple graphics tiles in flight; now you have multiple compute tiles in flight. It builds on many of the same lessons and concepts, which we’ve progressively patented as well.
We’ve talked a lot about high-quality graphics, with gaming as a major driver. There are interesting trends—foldable phones, larger screens, and the Steam Deck-style handheld-PC market being targeted by Intel, AMD, and others. Where do you see the markets you can address? Are you mainly focused on phones?
Beets: No. This really connects to the continuation of our DirectX support. We support the DirectX 12 API but still at DirectX 11 feature level. Internally, we use the whole Steam Proton and DXVK stack for running a lot of content, but you do run into feature gaps or the size differences between desktop GPUs and embedded GPUs. It’s one of our investment tracks. We’ve gone from doing essentially nothing on DirectX back to delivering DirectX 12 drivers, and we’ll keep closing that feature gap. Once we reach DirectX 12 feature level, it becomes much easier to go into those kinds of devices.
In the meantime, an existing market for us is more in China, where a lot of the cloud-gaming platforms are owned by the game makers themselves. They can adapt more directly to what the platform can do while keeping costs low.
We’ve been talking about gaming and new form factors. Where do you see the main growth markets? A lot of the historical markets are relatively flat. Smartphones aren’t racing ahead, and there are issues around memory constraints. What are Imagination’s big targets?
Liouti: There’s convergence between market segments as well. Cars have more mobile features; mobile devices have more PC features. Because there’s that convergence, we aim to support all of the market segments through a flexible architecture that scales up and down, while also providing distinct features for each segment. Automotive is one of our largest areas of focus and one where we have a very strong share. Our functional-safety story has always resonated and continues to resonate. For edge, mobile, and PC, we continue pushing both graphics and AI, and want to support more and more new architectures. Those AI features are becoming increasingly relevant.
You’re also right about memory pricing. We are seeing unit volumes affected, but at the same time, devices are becoming more premium. That drives device costs higher, but it also increases the value of the devices.
Is it possible for you to capture more of that value? It’s the classic problem for an IP company: How do I get my fair share of a $2,000 phone?
Liouti: Yes. It’s driven through a couple of parameters. Generally, you now get much more technology value and IP into each device. That’s extremely relevant in automotive, where we’ve seen an enormous amount of silicon added year on year, but we see it in other devices as well. Chip ASPs keep getting higher, not just because foundry costs are increasing, but because there is more area, more value, and more premium technology going into those chips. As a result, the revenue we get per device at Imagination keeps increasing. That is partly an artifact of ASP and partly an artifact of moving more customers from older IP into newer IP.
We still have a portion of royalty revenue coming from Series 7, 8, and 9. We’re now seeing B-Series and newer generations come through. Depending on the contract, our default is often a percentage of the ASP value, so we can participate in that increased value similarly to other soft-IP vendors.
What do we think?
GPUs already occupy a significant part of the die in many systems, while CPUs, NPUs, and other accelerators each bring their own memory, software, and integration overheads. Imagination’s answer is “converged acceleration”—move more AI capability into the GPU and allow customers to decide how much dedicated NPU hardware they still need. In some systems, that may mean collaboration between GPU and NPU; in others, customers may decide a larger GPU can replace the NPU altogether.
That reinforces the broader argument, made to us recently by Imagination’s CEO Markus Mosen, that Imagination’s value lies in flexible IP rather than in forcing customers towards a fixed silicon architecture. Dedicated accelerators are extremely efficient when their job is tightly defined; the problem begins when the market moves faster than the hardware. Imagination is betting that flexibility becomes more valuable as AI moves into consumer, automotive, and edge ecosystems.
The company’s historical advantage in tile-based graphics was fundamentally about locality: keeping data close to the processing hardware and avoiding expensive external-memory traffic. Much of the E-Series AI story follows the same line. On-chip storage is reused, AI data is tiled, weights can remain local, and graphics and neural operations can be intermixed without repeatedly writing data out to memory, thus saving power. This is not Imagination abandoning its graphics heritage to chase AI. It is adapting some of the architectural ideas that made PowerVR distinctive in the first place.
Memory is becoming one of the defining constraints on both AI performance and system cost. Imagination estimates that the GPU can consume very high bandwidth internally, but the useful performance of an LLM still depends heavily on how quickly the surrounding system can supply data. Its distinction between compute-heavy prefill and bandwidth-heavy decode is an interesting one: headline TOPS alone does not tell you whether an AI architecture will perform well in a real device.
Overall, there seems to be technical substance to the argument that Imagination’s independent-IP position could become increasingly valuable. The proposition is not simply we are not Arm, AMD, or Nvidia. It is that Imagination can provide increasingly capable GPU and AI technology while leaving customers in control of their architecture, software choices, and product differentiation.
That only works if the technology is competitive, and there are still gaps to close. DirectX support is an obvious example if Imagination wants to participate more seriously in PC-like devices, and they say they’re working on it. But the direction is coherent: improve the GPU, extend it into AI, make better use of memory, keep the software environment as open as possible, and allow the customer to decide what the final chip should look like.
LIKE WHAT YOU’RE READING? TELL YOUR FRIENDS; WE DO THIS EVERY DAY, ALL DAY.